
Alignment of large language models has traditionally centered on preference learning. Methods such as Reinforcement Learning from Human Feedback (Christiano et al., 2017), Direct Preference Optimization (Rafailov et al., 2023), and Identity Preference Optimization (Azar et al., 2023) require training data formatted as pairs of candidate responses generated for the exact same prompt , where is preferred over .
In real-world production environments, paired preference data is scarce and expensive to construct. User interactions in production applications, customer support platforms, and coding assistants generate pointwise, binary feedback: thumbs-up or thumbs-down ratings, accepted or rejected suggestions, and completed or abandoned sessions. Forcing this binary telemetry into pairwise formats requires synthetic generation, heuristic prompt matching, or offline tournament ranking, introducing noise, latency, and substantial data curation costs.
Kahneman-Tversky Optimization (KTO), introduced by Ethayarajh et al. (2024), eliminates the requirement for paired preferences. By framing language model alignment through the lens of behavioral economics and Prospect Theory, KTO directly maximizes the utility of model generations from unpaired binary feedback ().

The Behavioral Economics of Alignment: Prospect Theory and HALOs
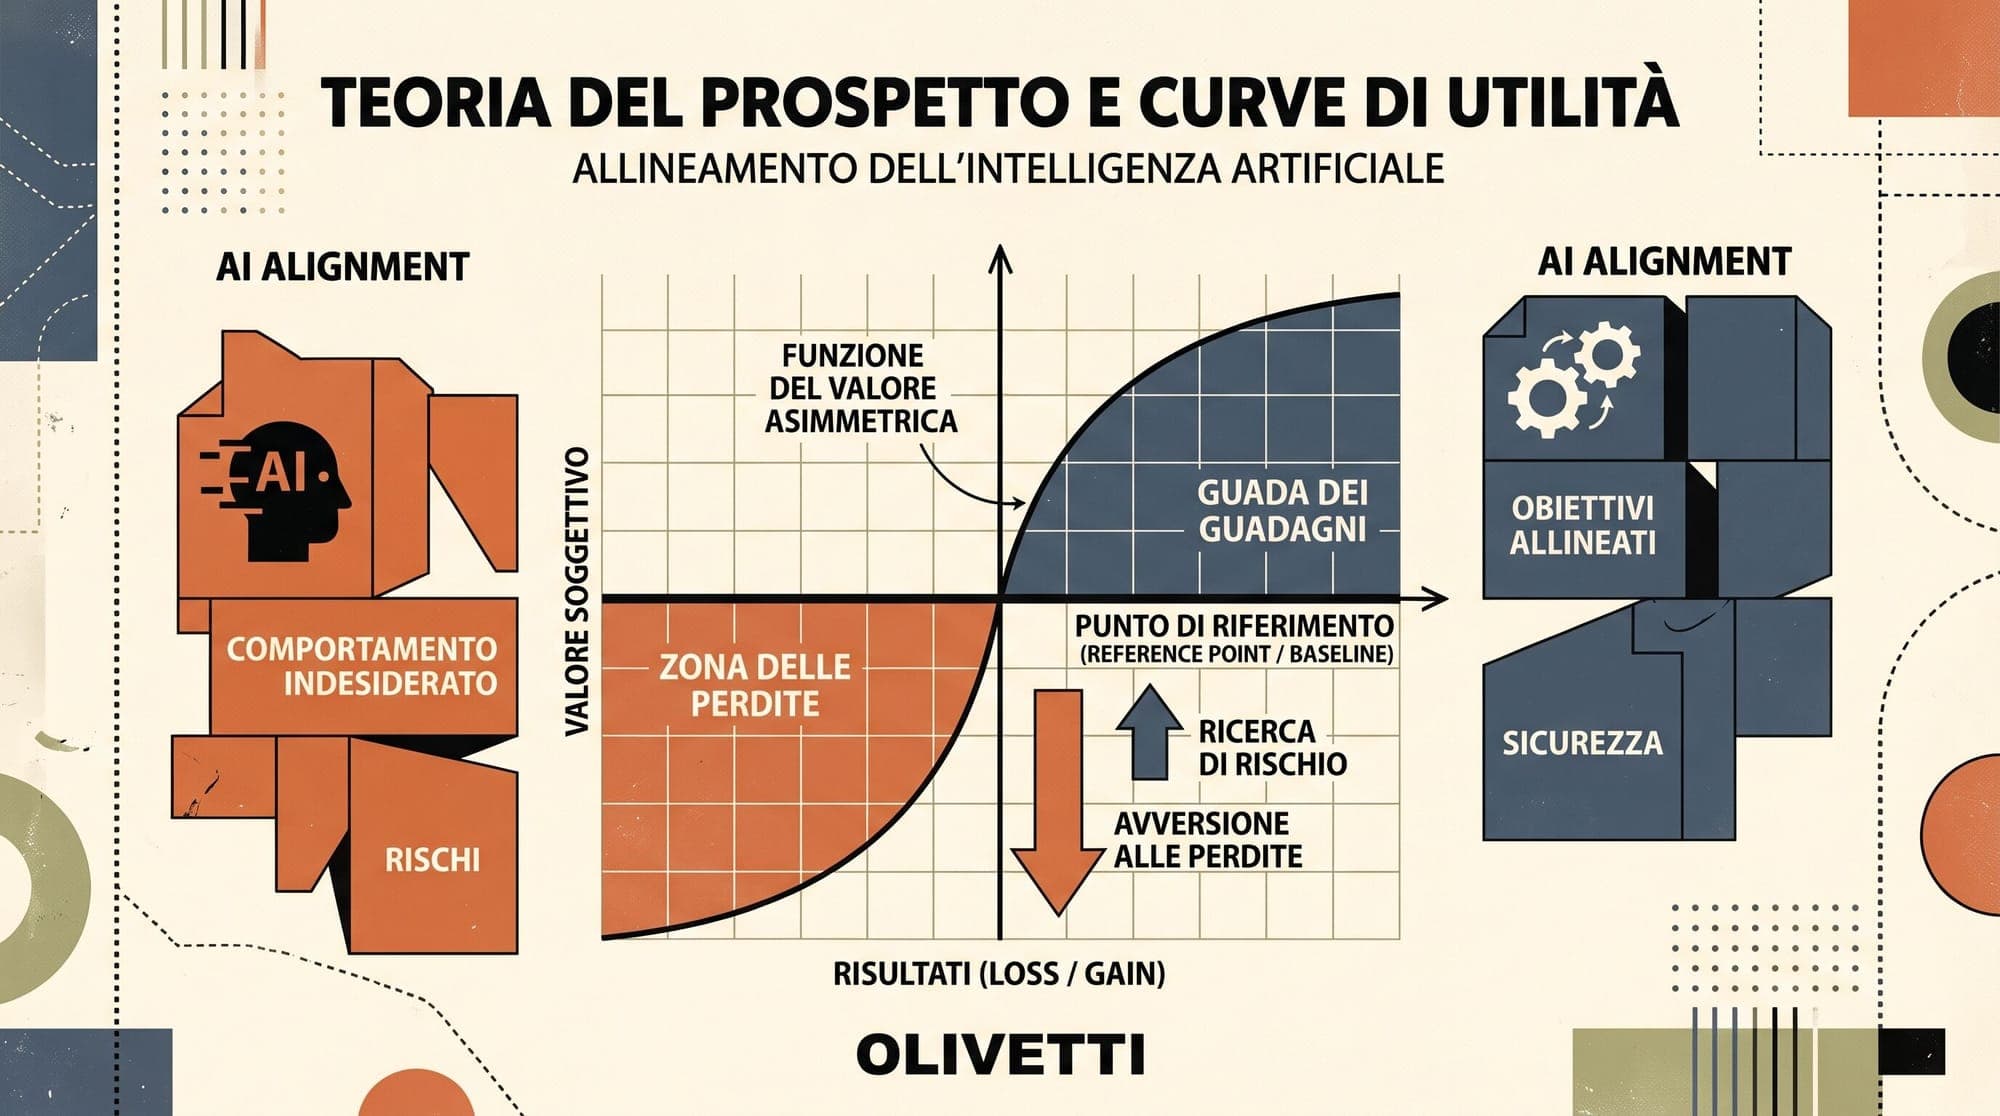
Standard expected utility theory posits that decision-makers evaluate options by multiplying objective probabilities by objective payouts. In contrast, Daniel Kahneman and Amos Tversky's Cumulative Prospect Theory (Kahneman & Tversky, 1979; Tversky & Kahneman, 1992) demonstrated that human judgment departs from expected value maximization in three systematic ways:
- Reference Dependence: Humans do not evaluate outcomes in absolute terms. They evaluate them as gains or losses relative to a neutral reference point .
- Loss Aversion: Losses loom larger than corresponding gains of equal magnitude. The psychological penalty of a loss is typically 1.5 to 2.5 times greater than the pleasure of an equivalent gain ().
- Diminishing Sensitivity: The marginal psychological impact of both gains and losses decreases as their distance from the reference point increases, yielding a value function that is concave for gains and convex for losses.
Ethayarajh et al. demonstrated that post-training alignment algorithms implicitly function as Human-Aware Loss Objectives (HALOs). A HALO is an optimization objective where the loss depends on an implicit reward function mapped through a human-like value function relative to a reference distribution .
While Direct Preference Optimization (DPO) and PPO-Clip qualify mathematically as HALOs, their underlying utility formulations remain tied to pairwise comparisons. KTO translates prospect theory directly into an explicit loss function that operates on individual prompt-completion pairs.
Mathematical Formulation of KTO
In the standard language modeling setting, let denote the parameterized policy being aligned, and let denote the reference model (typically the supervised fine-tuned checkpoint). The implicit reward of a completion given prompt is defined as the log-ratio of sequence likelihoods:
In a prospect-theoretic framework, human value is not determined by in isolation, but by its deviation from an expected reference point . In KTO, the reference point represents the policy's expected divergence from the reference model across all possible continuations:
The KTO Value Function
To avoid the numerical instability of the original polynomial exponent in Kahneman and Tversky's formulation, KTO adopts a logistic transformation that retains the essential properties of concavity in gains and convexity in losses:
Here:
- governs risk aversion, dictating how rapidly the value function saturates as the reward deviates from the reference point.
- and are weighting parameters controlling the model's sensitivity to desirable and undesirable outcomes, directly analogous to loss aversion coefficients.
- is the sigmoid function.
The Objective Function
The full KTO loss minimizes the expected difference between the maximum achievable utility and the realized utility across the dataset :
where when is desirable and when is undesirable.
KTO Optimization Mechanics:

Desirable Example (x, y_pos):
  Reward r_theta(x, y_pos) > z_0
  Value v(x, y_pos) -> lambda_D
  Gradient increases log pi_theta(y_pos|x) relative to pi_ref

Undesirable Example (x, y_neg):
  Reward r_theta(x, y_neg) < z_0
  Value v(x, y_neg) -> lambda_U
  Gradient decreases log pi_theta(y_neg|x) relative to pi_ref

Dynamic Anchor z_0:
  If policy indiscriminately inflates token probabilities,
  z_0 rises, neutralizing utility gains.
  The model is forced to isolate the specific features that drive desirability.
Microbatch Estimation of the Reference Point
Evaluating the exact sequence-level KL divergence during training would require generating autoregressive samples from at every step, reintroducing the runtime bottlenecks of online RL.
To maintain an entirely offline, differentiable training pipeline, KTO estimates across the microbatch. Given a microbatch of training pairs , KTO constructs mismatched prompt-completion pairs by shifting completions by one index: where .
The empirical reference point estimator is defined as:
Using mismatched completions prevents the estimator from being skewed by canonical target completions that carry extreme likelihood values. Gradients are not backpropagated through ; it serves solely as an adaptive baseline for loss saturation.
When KTO fine-tuning directly follows an SFT stage trained on the same positive data, initially matches , causing . In this scenario, setting provides a stable approximation without requiring an auxiliary forward pass.
Key Properties and Empirical Findings
Ethayarajh et al. evaluated KTO across model scales ranging from 1B to 30B parameters, including Pythia (Biderman et al., 2023), Llama (Touvron et al., 2023), Llama 3 (Dubey et al., 2024), and Qwen 2.5 (Yang et al., 2024).
Empirical Performance Across Benchmarks:

Model & Method           | MMLU (EM) | GSM8K (8-shot) | HumanEval (pass@1) | BBH (3-shot)
-----------------------------------------------------------------------------------------
Llama-3 8B (SFT)         | 57.2      | 39.0           | 30.1               | 46.3
Llama-3 8B (SFT + DPO)   | 58.2      | 40.0           | 30.1               | 44.1
Llama-3 8B (SFT + ORPO)  | 57.1      | 36.5           | 29.5               | 47.5
Llama-3 8B (SFT + KTO)   | 58.6      | 53.5           | 30.9               | 52.6
Llama-3 8B (KTO direct)  | 58.0      | 50.0           | 30.7               | 49.9
1. Parity and Superiority on Unpaired Data
When benchmark preference datasets (Anthropic-HH, Stanford Human Preferences, OpenAssistant) were decomposed into independent positive and negative examples, KTO matched or exceeded DPO's performance across open-ended evaluation (AlpacaEval, MT-Bench) and closed-ended reasoning tasks (GSM8K, BigBench-Hard). On mathematical reasoning with Llama-3 8B, KTO achieved 53.5% exact match on GSM8K compared to 40.0% for DPO.
2. Robustness to Extreme Data Imbalance
In production datasets, positive feedback often significantly outnumbers negative feedback, or vice versa. Pairwise methods fail when one class dominates because every training instance requires both a winner and a loser.
KTO handles class imbalances by tuning the ratio of loss weights:
where and represent the count of desirable and undesirable training examples. In empirical tests, KTO maintained full alignment performance even when 90% of desirable examples were withheld ( positive-to-negative ratio), provided was scaled proportionally.
3. Direct Alignment Without Supervised Fine-Tuning
For sufficiently capable pretrained base models, KTO can bypass the Supervised Fine-Tuning (SFT) phase entirely. Training Llama-3 8B and Qwen 2.5 3B directly with KTO from the base checkpoint yielded competitive win rates against SFT+DPO baselines, whereas running DPO directly on base models led to mode collapse and degenerate text generation.
Practical Engineering and Hyperparameter Guidelines
Implementing KTO in production fine-tuning pipelines requires adjustments relative to standard DPO configurations:
- Learning Rate: KTO operates on reference-adjusted pointwise margins rather than paired preference differences. Because is smaller in magnitude than , KTO requires higher learning rates. Optimal learning rates with AdamW typically range from to , roughly 5x to 10x higher than DPO defaults ().
- Risk Aversion Parameter : For models that have already undergone instruction fine-tuning, lower values () prevent excessive policy drift. When applying KTO directly to base models without prior SFT, higher values () provide stronger regularization.
- Batch Sizing: Microbatch size must be at least 2 () to enable mismatched sequence pairing for estimation. Effective batch sizes between 32 and 128 sequences provide stable gradient estimates.
- Memory and Sequence Packing: Because KTO processes individual completions rather than concatenated prompt-winner-loser triplets, memory consumption per forward pass is substantially lower than DPO. Variable-length sequences can be packed into uniform batches without wasting compute on cross-sequence padding between paired responses.
Alignment Paradigm Comparison
Comparison of Post-Training Alignment Paradigms:

Algorithm  | Data Format         | Reward Model | Reference Model | Online Sampling | Objective Family
--------------------------------------------------------------------------------------------------------
PPO (RLHF) | Unpaired / Paired   | Yes          | Yes             | Yes             | Reinforcement Learning
DPO        | Pairwise (yw > yl)  | No           | Yes             | No              | Implicit Margin (HALO)
IPO        | Pairwise (yw > yl)  | No           | Yes             | No              | Regularized Margin
ORPO       | Pairwise (yw > yl)  | No           | No              | No              | Odds Ratio Penalty
SimPO      | Pairwise (yw > yl)  | No           | No              | No              | Length-Normalized Margin
KTO        | Pointwise (y, +/-1) | No           | Yes             | No              | Prospect Theoretic (HALO)
Architectural Trade-Offs
KTO provides a direct bridge between operational user feedback and model optimization. By replacing the artificial constraint of preference pairs with a mathematically grounded model of human utility, KTO allows engineering teams to align models directly on telemetry logs, thumbs-up ratings, and curated binary demonstrations.
However, KTO is not an automatic replacement for all preference methods. In scenarios where data is collected through explicit side-by-side human evaluation (such as LMSYS Chatbot Arena), pairwise losses like DPO, SimPO, and ORPO remain well-aligned with the underlying data distribution. When user feedback is inherently pointwise, unpaired, and imbalanced, KTO provides superior data efficiency, simpler ingestion pipelines, and robust convergence properties.
Sources
- KTO: Model Alignment as Prospect Theoretic Optimization (Ethayarajh et al., 2024)
- Direct Preference Optimization: Your Language Model Is Secretly a Reward Model (Rafailov et al., 2023)
- Prospect Theory: An Analysis of Decision under Risk (Kahneman & Tversky, 1979)
- Advances in Prospect Theory: Cumulative Representation of Uncertainty (Tversky & Kahneman, 1992)
- Training Language Models to Follow Instructions with Human Feedback (Ouyang et al., 2022)
- A General Theoretical Paradigm to Understand Learning from Human Preferences (Azar et al., 2023)



