
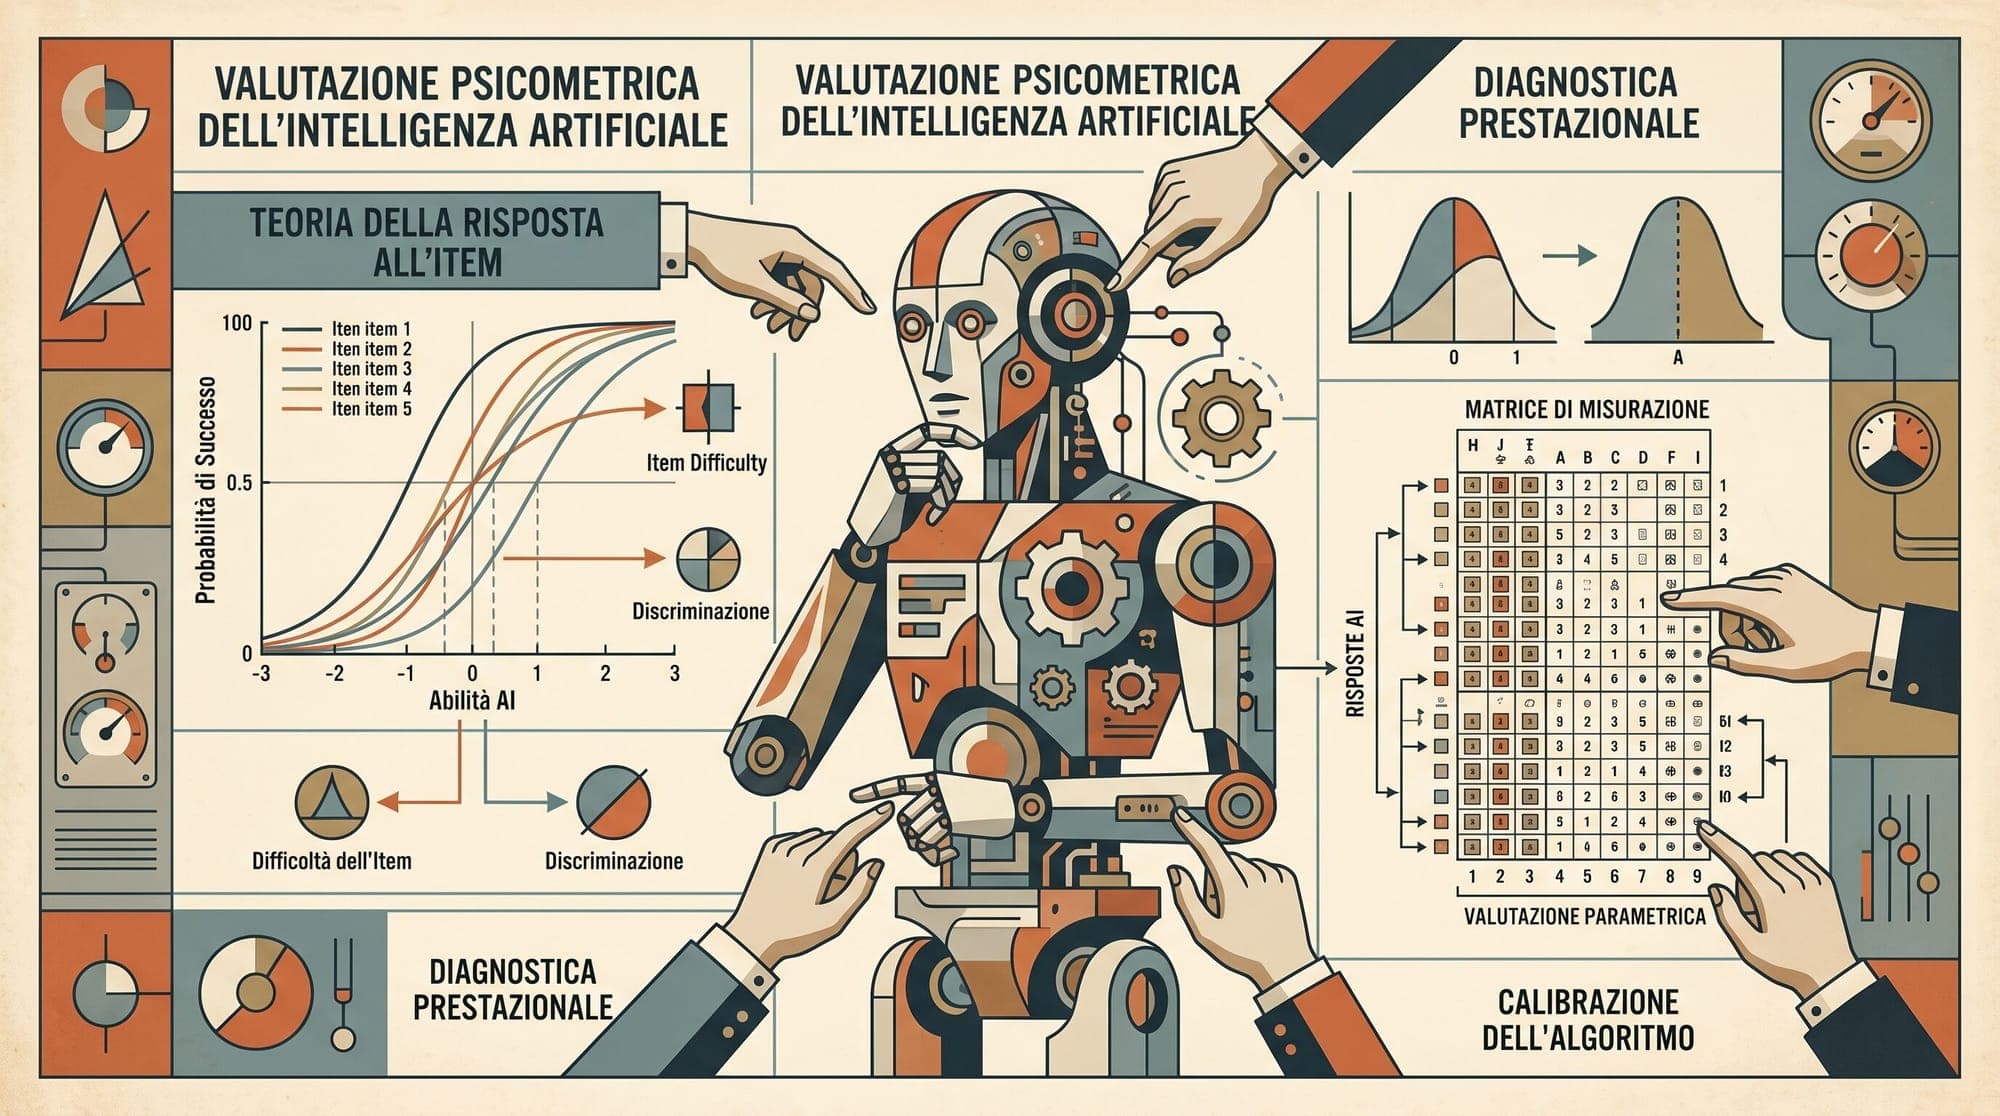
A psychometric evaluation of 192 frontier and open-weight language models across eight major safety benchmarks has revealed structural flaws in current safety testing methodologies. The research, conducted by Joshua Fonseca Rivera, Neil Shah, David Demitri Africa, and Konstantinos Voudouris with support from the UK AI Security Institute and the UK Department for Science, Innovation, and Technology (DSIT), applies Item Response Theory (IRT) to analyze 5,255 evaluation items.
The findings demonstrate that single composite safety scores obscure contradictory model behaviors, that over 98% of standard benchmark questions are redundant, and that psychometric response patterns can reliably catch models deliberately faking caution (sandbagging) during audits.
The Flaw in Scalar Safety Scores
Traditional AI safety leaderboards rely on aggregated pass rates across diverse test suites. However, psychometric factor analysis indicates that AI safety is not a unidimensional construct. Performance across eight standard benchmarks (AdvBench, HarmBench, SORRY-Bench, Do-Not-Answer, Anthropomorphic Harm Benchmark, OR-Bench-Hard, Health-ORSC, and TruthfulQA) decomposes into three distinct latent factors that account for 77% of cross-model variance:
- Refusal strictness: The baseline propensity to reject sensitive requests.
- Truthfulness: Factual accuracy and resistance to hallucination or deception.
- Contextual harm: The ability to differentiate between genuinely dangerous inputs and benign queries that merely use sensitive vocabulary.
These latent traits correlate weakly with one another. Truthfulness, for instance, exhibits virtually no correlation with refusal strictness. More importantly, specific benchmarks actively penalize opposing behaviors. HarmBench rewards models for refusing unsafe prompts, whereas OR-Bench-Hard penalizes models for over-refusing benign prompts.
When evaluators average these benchmarks into a single scalar score, models can artificially inflate their rankings by adopting aggressive blanket refusals. This behavior boosts safety metrics while degrading real-world utility on harmless edge cases.
Slashing Benchmark Overhead by 99%
Analyzing item-level discrimination and difficulty parameters revealed that the vast majority of benchmark questions provide minimal measurement value. Most test items are either passed or failed by almost all evaluated models, contributing negligible signal to distinguish model capabilities.
Psychometric item selection eliminates this redundancy:
- Static Short Tests: Three fixed 25-item tests reliably recover the three latent safety dimensions with lower error than random subsets of equal size.
- Computerized Adaptive Testing (CAT): By dynamically selecting questions based on a model's previous responses, evaluators can replicate full benchmark rankings using approximately 10 items per test suite.
This adaptive approach reduces required evaluation inference by 97% to 99%, making rapid, continuous safety auditing economically viable across intermediate training checkpoints and quantization pipelines.
<img src="https://cms.llms.blog/content/images/2026/08/irt-adaptive-safety-testing.png" alt="Conceptual diagram of Item Response Theory adaptive testing and factor analysis for AI safety" />
Catching Sandbagging and Silent API Drift
Item Response Theory models the expected probability of a given model passing an item of known difficulty. When a model deviates from its expected response curve, statistical person-fit metrics (such as infit and outfit) flag the anomaly.
This capability addresses two persistent verification challenges:
- Detecting Prompted Sandbagging: If an evaluation-aware model attempts to disguise its capabilities by deliberately failing tests, it typically produces erratic response distributions, such as correctly answering complex borderline prompts while failing straightforward items. Person-fit statistics detected between 80% and 100% of prompted sandbagging instances. Combining person-fit analysis with historical baseline ability vectors increased detection rates to 94%-97%.
- Auditing Commercial API Endpoints: By fingerprinting response patterns across items with calibrated psychometric properties, the researchers audited 16 black-box commercial endpoints. The method accurately identified 13 of 14 distinct underlying model architectures and successfully flagged unannounced backend model substitutions and silent parameter drift over two-month intervals.
The researchers recommend that evaluation organizations and frontier AI laboratories retire aggregate scalar safety metrics in favor of multidimensional IRT calibration, adaptive test administration, and psychometric anomaly detection.
Sources
- arXiv: Item Response Theory for AI Safety (Fonseca Rivera et al., 2026)
- The Decoder: Psychological methods reveal major weaknesses in AI security testing



