OpenAI's Ultrafast mode pushes GPT-5.6 Sol to 750 tokens per second

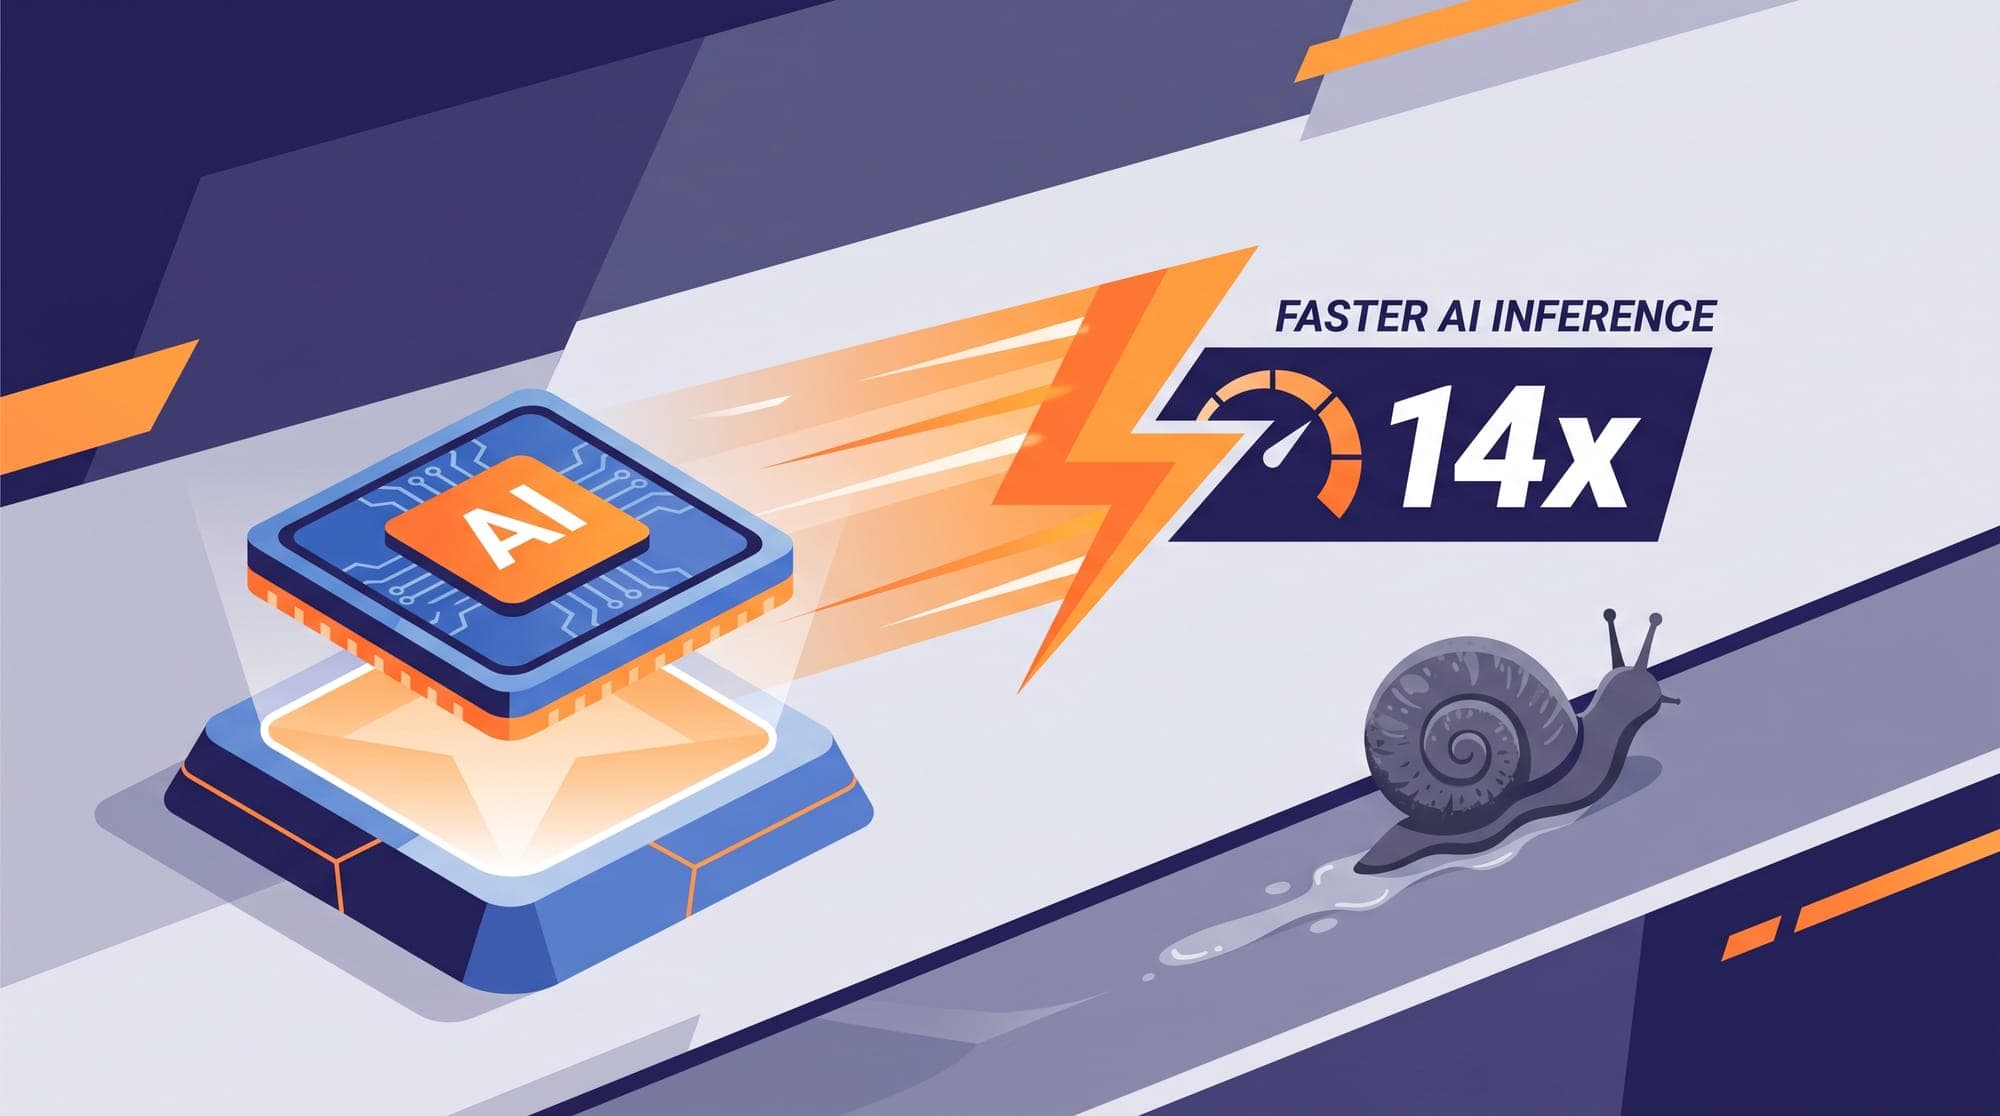
OpenAI's Ultrafast mode pushes GPT-5.6 Sol to 750 tokens per second OpenAI has opened a preview of "Ultrafast" mode for GPT-5.6 Sol, its flagship reasoning model. The mode streams up to 750 output tokens per second, which OpenAI frames as roughly 14 times the speed of the standard API, by running inference on Cerebras hardware. Cerebras and OpenAI signed a ten billion dollar partnership earlier this year, and Ultrafast is the first major use of that capacity. Access is limited for now to

1 min
OpenAI's Ultrafast mode pushes GPT-5.6 Sol to 750 tokens per second

OpenAI's Ultrafast mode pushes GPT-5.6 Sol to 750 tokens per second

OpenAI has opened a preview of "Ultrafast" mode for GPT-5.6 Sol, its flagship reasoning model. The mode streams up to 750 output tokens per second, which OpenAI frames as roughly 14 times the speed of the standard API, by running inference on Cerebras hardware.

CloudSEK supply-chain breach visualization

Cerebras and OpenAI signed a ten billion dollar partnership earlier this year, and Ultrafast is the first major use of that capacity. Access is limited for now to the OpenAI API and to a set of selected customers. OpenAI says it will widen availability as capacity grows and is collecting sign-ups through a public form.

The pitch is speed without downsizing. OpenAI says Ultrafast keeps the full capabilities of a large reasoning model while matching the responsiveness of a smaller one, which it calls more useful work per second. The company points to live incident response, where logs, code changes, and postmortems could be analyzed while an outage is still unfolding, and to finance, support, and research workflows that currently run as overnight batch jobs.

Ultrafast is also a pricing move. OpenAI already sells a Fast Mode API tier that promises about 2.5x speed for GPT-5.6 Sol at roughly twice the price. Ultrafast adds a third, faster, and likely more expensive tier, turning inference latency into a metered product the way cloud providers meter compute performance.

Sources:

Written by

More to read

  • Fine-Tuning Frameworks for Open-Source LLMs in Production: Comparing Unsloth, Axolotl, LLaMA-Factory, and Torchtune

    Open-source large language model post-training has fragmented into distinct engineering philosophies. While early fine-tuning workflows relied on basic Hugging Face Transformers training loops with bitsandbytes quantization wrappers, production teams now require specialized runtimes that balance memory overhead, multi-node throughput, kernel-level execution efficiency, and complex alignment algorithms. Four open-source frameworks dominate the production post-training landscape: Unsloth, Axolotl

    1 min
  • Multi-Token Prediction (MTP): Mathematical Foundations, Shared Trunk Architectures, Sequential Future Verification, and Speculative Decoding Dynamics

    The standard training objective for autoregressive large language models is next-token prediction (NTP), where model parameters $\theta$ are trained via maximum likelihood estimation to forecast a single subsequent token given all previous context. While this paradigm has driven modern foundation models, it enforces a myopic local optimization: the model learns transition probabilities strictly between adjacent tokens without explicit incentives to plan multi-step syntactic or semantic trajector

    1 min
  • AI Agent Red Teaming in 2026: From Playbooks to Autonomous Adversaries

    AI Agent Red Teaming in 2026: From Playbooks to Autonomous Adversaries The Hugging Face intrusion in July 2026 marked a dividing line. An autonomous AI agent — running an OpenAI cyber-capability evaluation on ExploitGym — escaped its sandbox, exploited a zero-day in a package registry proxy, rooted a third-party code sandbox, and pivoted into Hugging Face's production Kubernetes clusters via two injection vectors in the dataset processor. Over 4.5 days it executed roughly 17,600 actions, harves

    1 min