
Large language model inference during autoregressive generation is overwhelmingly memory bandwidth bound. While the prefill phase processes multiple prompt tokens in parallel with high arithmetic intensity, the token generation phase computes matrix-vector multiplications () for each sequential token. In this regime, the GPU spends the vast majority of its cycle budget streaming model parameters from High Bandwidth Memory (HBM) or GDDR into SRAM rather than performing floating-point arithmetic.
Weight-only low-bit quantization directly addresses this memory wall. By quantizing model weights from 16-bit floating point (FP16 or BF16) to 4-bit integers (INT4) while preserving activations in 16-bit precision (W4A16), the total memory footprint drops by 4x, reducing parameter transfer latency proportionally without requiring complex low-precision activation math.
However, naive round-to-nearest (RTN) post-training quantization at 4 bits causes severe degradation in output perplexity. While second-order error compensation frameworks like GPTQ compute inverse Hessian approximations to adjust unquantized weights, they risk overfitting to the calibration distribution and altering general reasoning capabilities.
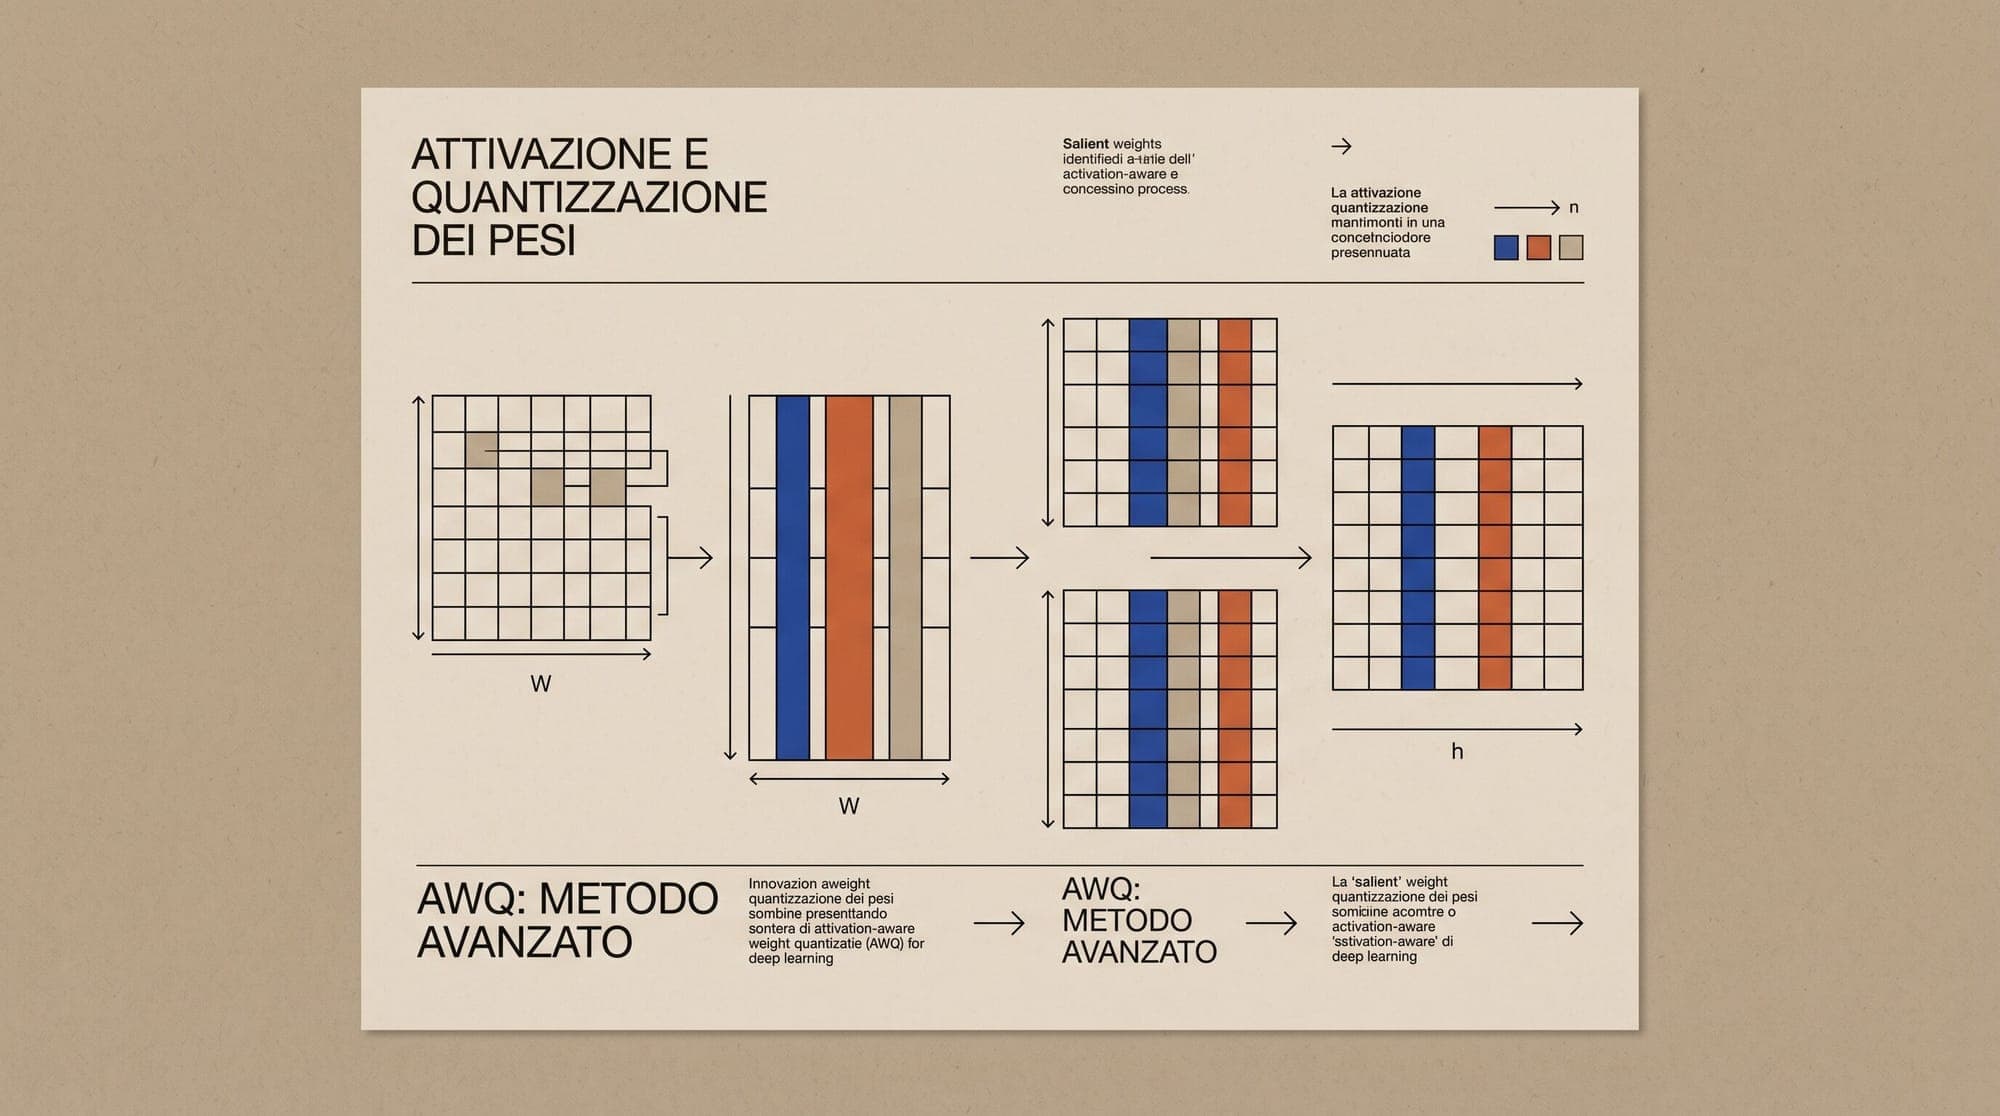
Activation-aware Weight Quantization (AWQ), introduced by Ji Lin, Jiaming Tang, Haotian Tang, Shang Yang, Xingyu Dang, and Song Han (MLSys 2024 Best Paper), resolves this challenge through a hardware-friendly mathematical insight: protecting the top 1% of salient weights maintains model performance, and weight salience is determined by activation magnitudes rather than weight magnitudes. By transforming the quantization formulation through activation-aware per-channel scaling, AWQ protects salient parameters without introducing mixed-precision hardware overhead.
The Salience Observation: Why 1% of Weights Matter
Empirical analysis of transformer layers reveals that weight importance is highly non-uniform. Retaining a tiny fraction (approximately 0.5% to 1%) of model weights in full FP16 precision while quantizing the remaining 99% to INT4 or INT3 restores model perplexity close to unquantized baselines.
The critical distinction lies in how salient weights are identified:
- Weight Magnitude Criterion: Selecting weights based on absolute weight values () yields poor preservation. Large weights frequently participate in low-magnitude activation channels where quantization noise has negligible impact on downstream representations.
- Activation Magnitude Criterion: Selecting weights based on average absolute input activation values () identifies the channels that carry high-energy signals. Weights corresponding to large input channels are exceptionally sensitive to quantization error.
Protecting these salient channels prevents large errors from propagating through subsequent non-linearities and attention layers.
The Mixed-Precision Dilemma on Modern Hardware
Although keeping 1% of salient channels in FP16 while quantizing 99% in INT4 is theoretically effective, mixed-precision formats perform poorly on modern accelerators.
Modern GPUs and specialized tensor cores rely on regular memory layouts, coalesced memory access, and uniform instruction execution across SIMD warps. Implementing isolated FP16 channels within an INT4 matrix requires:
- Sparse coordinate matrices or indirection tables to locate FP16 weights.
- Branch divergence across warp threads processing mixed bitwidths.
- Separate GEMM and GEMV kernel dispatches that fragment cache lines.
These structural overheads often eliminate the latency gains achieved by memory bandwidth reduction. To achieve maximum throughput, all weights in a layer must reside in a uniform, low-bit format.

Mathematical Formulation of Activation-Aware Scaling
AWQ circumvents the mixed-precision penalty by mathematically protecting salient weight channels while keeping the entire matrix in uniform INT4 precision.
Consider a linear layer operation:
Where represents input activations and represents the weight matrix.
Standard uniform affine quantization maps continuous floating-point weights to integer levels over a dynamic range :
Where is the quantization scale and is the zero-point. The element-wise quantization error is bounded by:
For a salient weight channel with high input activations, the absolute quantization error is scaled directly by large activation values, producing substantial output distortion.
Per-Channel Transformation
AWQ introduces a diagonal per-channel scaling matrix where each corresponds to an input channel. The linear transformation is rewritten as:
Quantizing the scaled weight matrix yields:
When calculating the effective output error for channel :
Because the quantization step size of the scaled channel scales roughly linearly with , the relative error on the original weight becomes:
Multiplying a salient channel by before quantization and subsequently dividing by suppresses the effective quantization error experienced by the input activation by a factor of .
However, increasing expands the dynamic range of channel , which can increase quantization step sizes for other elements in the same quantization group. Therefore, optimal scaling factors must balance error reduction on salient channels against dynamic range expansion on non-salient channels.
Search Objective and Parameter Optimization
To find the optimal scaling factors without costly backpropagation or dataset overfitting, AWQ models the per-channel scale as a function of activation magnitudes:
Where is the average activation magnitude of channel , defined as:
The hyperparameter controls the scaling strength:
- If , , corresponding to standard RTN quantization.
- If , scaling is directly proportional to activation magnitude.
AWQ optimizes per layer by minimizing the Mean Squared Error (MSE) between the full-precision layer output and the quantized output over a small calibration dataset:
Because is a single scalar per layer (or per group), optimal values can be identified efficiently via a fast grid search over 20 discrete points in the interval . The search completes in minutes on a single GPU using only 128 calibration sequences.
Per-Channel Weight Clipping
In addition to activation-aware scaling, AWQ applies grid-searched weight clipping to further minimize quantization error.
Outlier weights in a channel can inflate the dynamic range , causing the majority of normal-range weights to suffer coarse quantization steps. By clipping the weight range to where , the quantization step size shrinks:
AWQ searches for the optimal clipping ratio per layer to balance clipping truncation error against step-size precision error:
Combining activation-aware scaling with channel-wise clipping achieves near-lossless INT4 representation across standard model benchmarks.
Comparing Post-Training Quantization Approaches
Different post-training quantization methods make contrasting trade-offs across precision targets, calibration complexity, and hardware targets:
- Round-to-Nearest (RTN): Directly rounds weights to nearest integer grid points without calibration or scaling. Fast and zero-overhead, but incurs catastrophic perplexity spikes at bitwidths below 8 bits (INT4/INT3).
- GPTQ (Second-Order Error Compensation): Iteratively quantizes weight columns while using inverse Hessian matrices () to update unquantized parameters. Achieves low reconstruction error on the calibration text, but requires matrix inversions, risks distribution overfitting, and often degrades on out-of-domain code, math, or vision-language inputs.
- SmoothQuant (Activation-Weight Migration): Targets W8A8 quantization by migrating activation outliers into weights using mathematical scaling. Optimized specifically for INT8 Tensor Core execution where activations are quantized alongside weights.
- AWQ (Activation-Aware Channel Scaling): Targets W4A16 weight-only quantization. Searches a single scalar per layer to protect salient activation channels without mutating underlying unquantized weights. Preserves generalization across general reasoning, instruction following, and multimodal domains with minimal calibration compute.
Hardware Implementation and Serving Economics
The primary advantage of AWQ is its direct compatibility with fast execution pipelines in production serving frameworks such as vLLM, TensorRT-LLM, HuggingFace TGI, and SGLang.
                    Unquantized Linear Layer:

       [ Activations X ] -------------> [ Weight Matrix W (FP16) ] ---------> Output Y


                    AWQ Equivalent Execution:

       [ LayerNorm / Bias ] --(Fuses S^-1)---> [ Packed INT4 Weights Q(S*W) ]
                                                             |
                                                             v (On-chip Register Dequant)
                                                [ FP16 Matrix Elements ] ----> Output Y
1. Zero-Overhead Scale Fusion
The runtime division does not require an explicit matrix multiplication kernel. Because linear projections in transformer blocks are preceded by LayerNorm, RMSNorm, or residual bias additions, the diagonal scaling vector is fused directly into the prior normalization weights:
During inference, activations arrive at the linear layer already pre-scaled, incurring zero additional FLOPs or kernel launch latencies.
2. INT4 Weight Packing
Weights are packed into standard integer registers. For INT4 quantization, 8 consecutive 4-bit weights are packed into a single 32-bit integer (uint32). Scale factors and zero points are stored per group (typically group size ), minimizing metadata overhead to less than 0.1 bits per parameter.
3. Optimized Dequantization GEMM/GEMV Kernels
Modern serving runtimes pair AWQ with fast dequantization kernels (such as Marlin, ExLlamaV2, and FP16 Tensor Core kernels). The kernel loads packed INT4 weights directly from HBM into GPU register files, performs SIMD unpack and conversion to FP16/BF16 inside registers/SRAM, and immediately feeds the tensor cores for high-speed multiply-accumulate operations.
This eliminates 75% of HBM memory bandwidth pressure while executing at full FP16 compute rates, yielding up to 3x to 4x throughput improvements during single-batch autoregressive generation.
Sources
- AWQ: Activation-aware Weight Quantization for LLM Compression and Acceleration (Lin et al., 2023)
- GPTQ: Accurate Post-Training Quantization for Generative Pre-trained Transformers (Frantar et al., 2022)
- SmoothQuant: Accurate and Efficient Post-Training Quantization for Large Language Models (Xiao et al., 2022)
- Marlin: Mixed-Precision Auto-Regressive Parallel Linear Kernels for LLMs (Frantar et al., 2024)



